
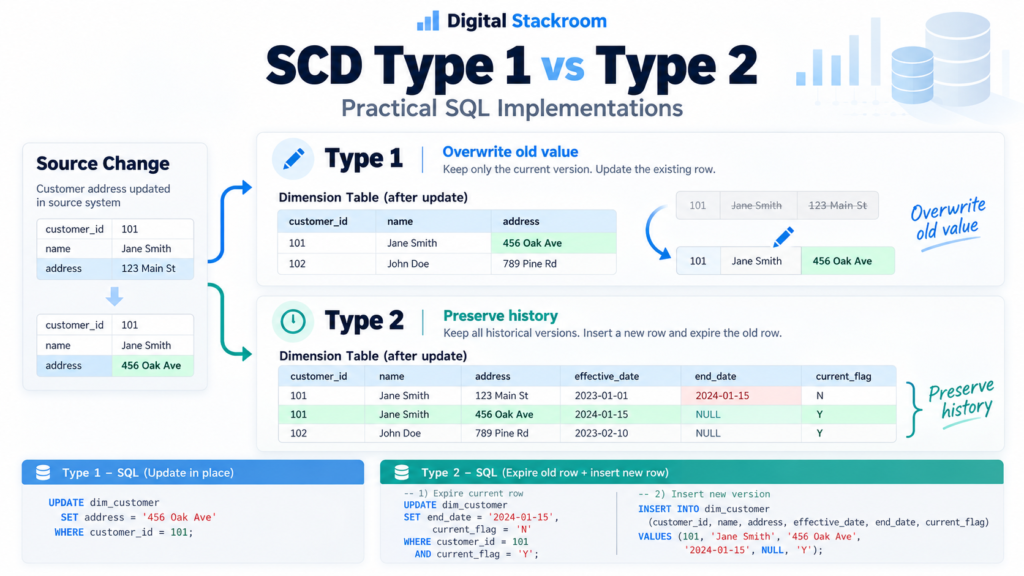
In data warehousing and analytical dimensional modeling, source system data is rarely static. Customers relocate to new regions, enterprise accounts transition between service tiers, and product SKUs change pricing tiers or category classifications.
When these upstream business attributes change, how your data warehouse reflects the change determines whether your financial reporting remains historically accurate or becomes quietly corrupt.
If an enterprise client who generated $100,000 in revenue while designated as a “Mid-Market” account is upgraded to “Enterprise” today, should historical revenue reports reattribute their past transactions to “Enterprise”?
Answering this architectural question requires implementing Slowly Changing Dimensions (SCD)—specifically choosing between SCD Type 1 (Overwriting) and SCD Type 2 (Historical Versioning).
Table of Contents
1. Problem Statement: The Cost of Attribute Mutation
Consider an analytics pipeline tracking sales commissions by territory. A sales representative, Alice, manages the North America West region throughout 2025, closing $2 million in revenue. On January 1, 2026, Alice is promoted to lead North America East.
Upstream Source Mutation:
ID: 104 | Name: Alice | Region: "NA-West"  ──►  ID: 104 | Name: Alice | Region: "NA-East"
If your data pipeline runs a naive synchronization:
SQL
-- Blind overwrite (Anti-Pattern if historical context matters)
UPDATE dim_sales_rep
SET region = 'NA-East', updated_at = NOW()
WHERE rep_id = 104;
The Analytical Consequences
- Historical Distortion: Running a retrospective 2025 revenue report by territory now attributes Alice’s $2 million to NA-East, creating an artificial spike in eastern revenue while falsely wiping out western quota achievements.
- Loss of Auditability: There is no mechanism to determine which territory Alice was responsible for on a specific historical transaction date.
- Broken Metric Consistency: Executive dashboards will show shifting baseline historical numbers every time dimension attributes change upstream—see our principles for building actionable Looker Studio executive dashboards.
Preventing this breakdown requires establishing a clear dimensional strategy for handling changes.
2. Architectural Comparison: SCD Type 1 vs. SCD Type 2
SCD TYPE 1 (Overwrite):
┌────────┬────────┬──────────┐
│ Rep_ID │ Name   │ Region   │  ──► Overwrites "NA-West" directly with "NA-East".
├────────┼────────┼──────────┤      Historical value is destroyed permanently.
│ 104    │ Alice  │ NA-East  │
└────────┴────────┴──────────┘

SCD TYPE 2 (Row Versioning with Validity Windows):
┌────────────┬────────┬────────┬──────────┬────────────┬────────────┬───────────┐
│ Rep_Key    │ Rep_ID │ Name   │ Region   │ Start_Date │ End_Date   │ Is_Active │
├────────────┼────────┼────────┼──────────┼────────────┼────────────┼───────────┤
│ 1001 (Sur) │ 104    │ Alice  │ NA-West  │ 2025-01-01 │ 2026-01-01 │ FALSE     │
│ 1002 (Sur) │ 104    │ Alice  │ NA-East  │ 2026-01-01 │ 9999-12-31 │ TRUE      │
└────────────┴────────┴────────┴──────────┴────────────┴────────────┴───────────┘
SCD Type 1 (In-Place Overwrite)
SCD Type 1 overwrites old data with current values. No history is preserved.
- Mechanism: Existing rows are updated directly via primary key matches.
- When to Use: Correcting data errors (e.g., fixing a typo in a customer’s legal name or phone number) or syncing attributes where past states carry zero analytical significance.
SCD Type 2 (Historical Versioning)
SCD Type 2 tracks full historical lineage by creating a new record every time a tracked attribute changes.
- Mechanism: The previous record’s validity window is closed by setting an
end_date, and a new record is inserted with a synthetic Surrogate Key, a newstart_date, and an open-ended validity indicator. - When to Use: Core business dimensions where metric attribution depends on the state of the entity at the time a transaction occurred (customer tier, sales rep territory, product pricing class, subscription plan).
3. Comparison Matrix
| Dimension | SCD Type 1 (Overwrite) | SCD Type 2 (Row Versioning) |
| History Retention | None. Only current state is preserved. | Full chronological audit trail of all mutations. |
| Storage Impact | Constant (Row count matches source table). | Growing (Row count expands with every attribute change). |
| Key Architecture | Natural Business Key (customer_id). | Requires Surrogate Key (customer_sk) + Natural Key. |
| ETL Complexity | Low (Single UPDATE or UPSERT). | High (Two-phase update/insert or complex MERGE). |
| Fact Table Joins | Direct 1:1 join on Natural Key. | Join on Natural Key + Point-in-Time Date Range: fact_date BETWEEN start_date AND end_date. |
| Query Performance | Faster; smaller indexes, smaller tables. | Slower if validity ranges are unindexed on large tables. |
4. Hands-On PostgreSQL Implementation: Building SCD Type 1
SCD Type 1 is straightforward and can be achieved with modern SQL ON CONFLICT (or UPSERT) logic.
Step 1: Create the Dimension Table
SQL
CREATE TABLE dim_customer_type1 (
    customer_id INT PRIMARY KEY, -- Natural Key
    full_name VARCHAR(100) NOT NULL,
    email VARCHAR(150) NOT NULL,
    tier VARCHAR(50) NOT NULL,
    last_updated_at TIMESTAMP NOT NULL DEFAULT NOW()
);
Step 2: Implement the Type 1 Ingestion Pipeline
When staging data arrives from source extracts:
SQL
-- Staging table representing incoming extract
CREATE TEMP TABLE staging_customer (
    customer_id INT,
    full_name VARCHAR(100),
    email VARCHAR(150),
    tier VARCHAR(50)
);

INSERT INTO staging_customer VALUES
(42, 'Marcus Vance', 'marcus@example.com', 'ENTERPRISE');

-- SCD Type 1 UPSERT Pipeline
INSERT INTO dim_customer_type1 (customer_id, full_name, email, tier, last_updated_at)
SELECT
    s.customer_id,
    s.full_name,
    s.email,
    s.tier,
    NOW()
FROM staging_customer s
ON CONFLICT (customer_id)
DO UPDATE SET
    full_name = EXCLUDED.full_name,
    email = EXCLUDED.email,
    tier = EXCLUDED.tier,
    last_updated_at = NOW();
5. Hands-On PostgreSQL Implementation: Building SCD Type 2
SCD Type 2 requires a disciplined schema structure featuring surrogate keys, explicit temporal boundaries, and active flag indicators.
Step 1: Create the SCD Type 2 Dimension Table
SQL
CREATE TABLE dim_customer_type2 (
    customer_sk BIGINT GENERATED ALWAYS AS IDENTITY PRIMARY KEY, -- Surrogate Key
    customer_id INT NOT NULL,                                     -- Natural Business Key
    full_name VARCHAR(100) NOT NULL,
    email VARCHAR(150) NOT NULL,
    tier VARCHAR(50) NOT NULL,
    effective_start_date DATE NOT NULL,
    effective_end_date DATE NOT NULL DEFAULT '9999-12-31',
    is_current BOOLEAN NOT NULL DEFAULT TRUE
);

-- Optimize point-in-time joins and current-state filtering
CREATE INDEX idx_dim_cust_natural_current
ON dim_customer_type2 (customer_id, is_current);

CREATE INDEX idx_dim_cust_effective_range
ON dim_customer_type2 (customer_id, effective_start_date, effective_end_date);
Step 2: Ingest Initial Records (Day 1)
SQL
INSERT INTO dim_customer_type2 (
    customer_id, full_name, email, tier, effective_start_date, effective_end_date, is_current
)
VALUES
(104, 'Alice Chen', 'alice@company.com', 'MID-MARKET', '2025-01-01', '9999-12-31', TRUE);
Step 3: Execute an SCD Type 2 Transaction Pipeline (Day 2 Mutation)
Suppose on 2026-01-01, Alice is promoted from MID-MARKET to ENTERPRISE. We must:
- Identify records that have changed.
- Expire the existing active version by closing its
effective_end_dateand markingis_current = FALSE. - Insert a new record containing the updated attributes with
effective_start_date = '2026-01-01'.
In PostgreSQL 15+ (or using CTEs in earlier versions), this can be executed cleanly in an atomic transaction:
SQL
-- Step 3A: Create staging data with the attribute change
CREATE TEMP TABLE staging_customer_changes (
    customer_id INT,
    full_name VARCHAR(100),
    email VARCHAR(150),
    tier VARCHAR(50),
    change_effective_date DATE
);

INSERT INTO staging_customer_changes VALUES
(104, 'Alice Chen', 'alice@company.com', 'ENTERPRISE', '2026-01-01');

-- Step 3B: Atomic Two-Phase Pipeline
BEGIN;

-- 1. Expire current active records where tracked attributes changed
UPDATE dim_customer_type2 target
SET
    effective_end_date = stage.change_effective_date,
    is_current = FALSE
FROM staging_customer_changes stage
WHERE target.customer_id = stage.customer_id
  AND target.is_current = TRUE
  AND (
      target.full_name <> stage.full_name OR
      target.email <> stage.email OR
      target.tier <> stage.tier
  );

-- 2. Insert new version rows for modified and brand-new customers
INSERT INTO dim_customer_type2 (
    customer_id,
    full_name,
    email,
    tier,
    effective_start_date,
    effective_end_date,
    is_current
)
SELECT
    stage.customer_id,
    stage.full_name,
    stage.email,
    stage.tier,
    stage.change_effective_date,
    '9999-12-31'::DATE,
    TRUE
FROM staging_customer_changes stage
LEFT JOIN dim_customer_type2 current_dim
  ON stage.customer_id = current_dim.customer_id
  AND current_dim.is_current = TRUE
WHERE current_dim.customer_id IS NULL -- Truly new record
   OR (
      current_dim.full_name <> stage.full_name OR
      current_dim.email <> stage.email OR
      current_dim.tier <> stage.tier
   );

COMMIT;
6. Querying SCD Type 2 Dimensions
Scenario A: Real-Time Current Reporting
To report on the business as it stands today, filter directly on is_current = TRUE:
SQL
SELECT
    customer_id,
    full_name,
    tier
FROM dim_customer_type2
WHERE is_current = TRUE;
Scenario B: Point-in-Time Fact Joins (Historical Integrity)
When joining fact transactions to dimensions, join on the Natural Key and constrain by the transaction date:
SQL
SELECT
    f.transaction_id,
    f.transaction_date,
    f.amount,
    d.tier AS tier_at_time_of_sale
FROM fact_sales f
INNER JOIN dim_customer_type2 d
    ON f.customer_id = d.customer_id
   AND f.transaction_date >= d.effective_start_date
   AND f.transaction_date < d.effective_end_date;
Transactions executed in 2025 automatically map to MID-MARKET, while transactions occurring after 2026-01-01 join cleanly to ENTERPRISE.
7. Hybrid SCD (Type 6): Best of Both Worlds
In large analytical platforms, stakeholders often request both views simultaneously:
- “I want to see sales grouped by the customer tier at the moment of the deal.” (SCD Type 2)
- “I also want to see historical sales grouped by the customer’s current tier today.” (SCD Type 1)
This pattern is known as SCD Type 6 ($1 + 2 + 3 = 6$). It tracks historical rows like Type 2, but appends an additional column to every row storing the current attribute value:
SQL
-- SCD Type 6 Pattern Schema
CREATE TABLE dim_customer_type6 (
    customer_sk BIGINT GENERATED ALWAYS AS IDENTITY PRIMARY KEY,
    customer_id INT NOT NULL,
    full_name VARCHAR(100) NOT NULL,
    historical_tier VARCHAR(50) NOT NULL, -- Value during this specific window (Type 2)
    current_tier VARCHAR(50) NOT NULL,    -- Overwritten across ALL rows on change (Type 1)
    effective_start_date DATE NOT NULL,
    effective_end_date DATE NOT NULL,
    is_current BOOLEAN NOT NULL
);
When Alice transitions to ENTERPRISE, her old record keeps historical_tier = 'MID-MARKET', but the pipeline updates current_tier = 'ENTERPRISE' across all rows sharing customer_id = 104. This allows analysts to pivot between historical perspective and current organizational structure in a single query without complex self-joins.
8. Architectural Decision Framework
An attribute changes in the operational source system:
├── Is the change a bug fix or typo correction (e.g., misspelled name)?
│    └── YES ──► Use SCD Type 1 (Overwrite record in place).
│
├── Does historical financial reporting require knowing the attribute's value at transaction time?
│    ├── NO  ──► Use SCD Type 1 (Simpler ETL, smaller table footprint).
│    └── YES ──► Does leadership require both historical AND modern attribution?
│                 ├── NO  ──► Use SCD Type 2 (Surrogate key + effective dates).
│                 └── YES ──► Use SCD Type 6 (Track version history + current state column).
Summary Checklist for Production Data Pipelines
- Always Use High-Sentinel End Dates: Default
effective_end_dateto'9999-12-31'rather thanNULL. Joining onf.date BETWEEN d.start AND COALESCE(d.end, NOW())prevents query planners from leveraging index bounds efficiently. - Never Overwrite Surrogate Keys: The primary key of an SCD Type 2 table must be an incrementing synthetic surrogate key, never the source natural key.
- Index Temporal Ranges: Always create composite indexes on
(natural_key, effective_start_date, effective_end_date)to prevent sequential scans during fact-table ETL loads. - Isolate Pipelines in Transactions: Expiring old records and inserting new records must happen inside an explicit atomic database transaction (
BEGIN...COMMIT) to avoid partial update states.