Video creates a strange problem for artificial intelligence.
A ten-page document contains a limited amount of information.
A ten-minute video contains:
- thousands of frames
- spoken audio
- background sounds
- subtitles
- objects moving through time
- scene changes
- visual text
- actions lasting fractions of a second
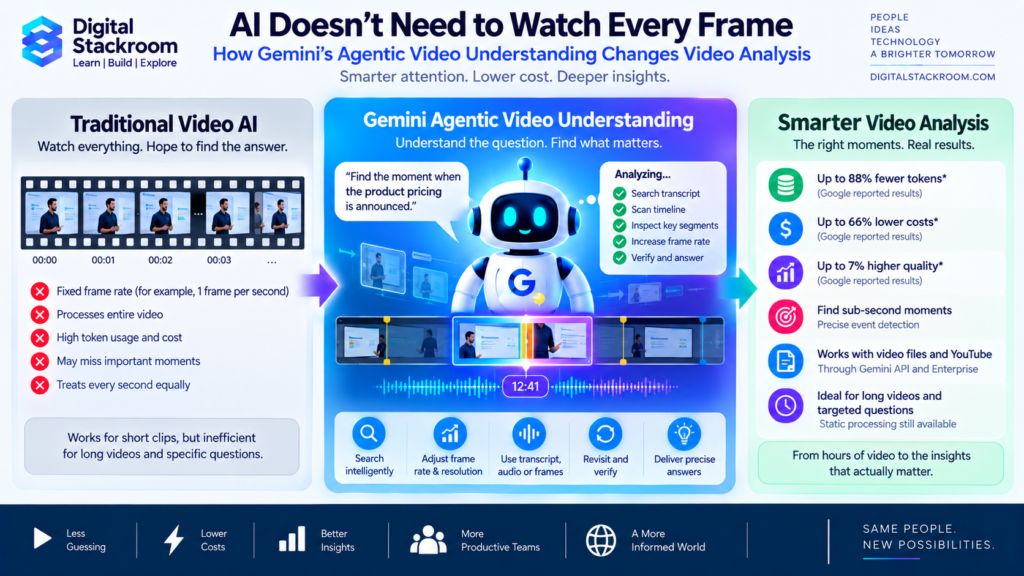
Traditional multimodal AI has often dealt with this by sampling video at a fixed rate.
For example:
one frame every second.
The model receives those sampled frames along with audio or transcript information and tries to understand what happened.
That works surprisingly well.
But it has two obvious weaknesses.
First, the model may process enormous amounts of information that have nothing to do with the question.
Second, an important event may happen between the sampled frames.
Google is now trying a different approach.
On September 1, 2026, Google introduced Gemini agentic video understanding, allowing Gemini to decide dynamically:
- where in the video to look
- which segment deserves closer inspection
- whether it needs frames, audio, or transcript
- what frame rate to use
- whether to revisit part of the video
- what resolution is appropriate
Instead of blindly consuming an entire video at a fixed frame rate, the model can investigate the video according to the question it is trying to answer.
That changes the video-analysis model from:
Watch everything → search for the answer
to:
Understand the question → decide where to look → inspect → verify → answer
Google reports that on its evaluations this approach can use up to 88% fewer tokens, reduce costs by up to 66%, and improve quality by up to 7%. Those are Google’s benchmark results, not guarantees for every workload.
The larger idea may matter even more than those numbers.
AI is beginning to decide what information is worth paying attention to before fully processing it.
Table of Contents
The Short Answer
Traditional video understanding usually works something like this:
Video
↓
Sample frames at fixed intervals
↓
Process audio/transcript
↓
Place everything into model context
↓
Answer question
Gemini’s agentic approach adds an investigation loop:
Question
↓
Develop search strategy
↓
Navigate timeline
↓
Load relevant transcript/audio/frames
↓
Adjust frame rate or resolution
↓
Inspect suspicious or important moments
↓
Answer
The model does not necessarily need to load the entire video into its working context.
Google’s current Gemini API documentation says agentic processing can dynamically navigate the timeline and selectively load:
- transcript
- frames
- audio
depending on what is required. It can also alter frame rates and resolution during the investigation.
That makes the model behave less like someone forced to watch an entire recording from beginning to end and more like an investigator who knows how to:
skim → search → zoom in → replay → verify.
Why Video Is Expensive for AI
Consider a 60-minute meeting.
If a system samples one frame every second, that creates:
3,600 visual frames
before we even consider audio or text.
Google’s current documentation estimates static low-resolution video processing at roughly 100 tokens per second, including frames and audio, and roughly 300 tokens per second at high media resolution.
At scale, video becomes expensive quickly.
Now imagine an enterprise analyzing:
10,000 hours of recordings.
The problem is no longer simply:
Can the model understand video?
It becomes:
Can the model understand video without processing huge amounts of irrelevant information?
This is where selective attention becomes economically important.
Traditional Static Video Processing
Google calls the conventional mode static processing.
By default, Gemini extracts video frames at approximately:
1 frame per second
and places them into context in a single pass.
Conceptually:
00:00 → frame
00:01 → frame
00:02 → frame
00:03 → frame
…
until the end.
This approach has advantages.
It is:
- predictable
- simple
- useful for short clips
- appropriate when broad coverage matters
- easier to reason about
But it treats every second approximately equally.
The model processes:
important event
and:
five minutes of nothing happening
using roughly the same sampling strategy.
That is inefficient for many questions.
The One-Frame-Per-Second Problem
Imagine a security video.
At:
12:41.20
a person removes an item from a shelf.
By:
12:41.80
the action is complete.
If your fixed sampling happens at:
12:41.00
and:
12:42.00
neither frame may clearly show the event.
The system could miss it.
Google specifically highlights sub-second moment retrieval as one of the capabilities improved by agentic video understanding.
Instead of keeping the same frame rate for the entire recording, the agent can determine:
Something relevant appears to happen here.
and then inspect that small interval more closely.
Digital Stackroom Framework: Static Video AI vs Agentic Video AI
The difference can be summarized like this.
| Stage | Static Video AI | Agentic Video AI |
|---|---|---|
| Start | Receive entire video | Receive video + question |
| Timeline strategy | Fixed | Dynamic |
| Frame rate | Predetermined | Can adapt |
| Transcript use | Broad ingestion | Selective |
| Audio use | Broad ingestion | On demand |
| Video segments | Process broadly | Navigate selectively |
| Attention | Uniform-ish | Goal directed |
| Best suited for | Short/general video analysis | Long videos and targeted questions |
| Token usage | Potentially high | Can be significantly lower |
| Time to first response | Often predictable | Can be slower for short clips due to investigation |
| Investigation | One-pass | Multi-step |
Google’s documentation explicitly notes that agentic processing can have slightly higher time to first token for short videos because the system performs internal reasoning and tool round-trips before answering.
So agentic mode is not automatically better for every workload.
How Gemini Agentic Video Understanding Works
The central idea is surprisingly intuitive.
Imagine asking:
“At what point in this three-hour football match did the goalkeeper first receive treatment?”
A static model could process the entire video.
An agentic model can instead reason:
- I need to locate a medical-treatment event.
- Search the timeline broadly.
- Inspect transcript/audio for relevant cues.
- Load frames around candidate moments.
- Increase temporal resolution.
- verify the event.
- return the timestamp.
The model effectively creates its own video-search plan.
Google describes this as a goal-directed process where Gemini dynamically decides what to watch, at what speed, and through which modality.
That word—modality—is important.
A Video Is Not Just Frames
Video is actually several information streams combined.
Visual stream
Objects, movement, faces, actions, text.
Audio stream
Speech, music, alarms, impact sounds.
Transcript
A compressed textual representation of spoken language.
Different questions need different streams.
Suppose you ask:
“What reason does the presenter give for delaying the launch?”
The transcript may provide most of the answer.
There may be little reason to inspect thousands of high-resolution frames.
Now ask:
“At what moment does the red indicator light begin flashing?”
The transcript may be useless.
Frames matter.
Now ask:
“When does the machine begin making an unusual grinding noise?”
Audio matters.
Agentic processing can choose accordingly.
The Real Optimization Is Selective Attention
This leads to a useful mental model.
Traditional processing asks:
What information exists in the video?
Agentic processing asks:
What information do I need to answer this question?
That is a much more powerful abstraction.
It resembles how humans work.
If someone gives you a three-hour recording and asks:
“What was the final score?”
you probably do not watch all three hours.
You jump near the end.
If they ask:
“Was the second goal offside?”
you navigate to that specific event and replay it carefully.
If they ask:
“How did the team’s strategy change throughout the match?”
you need a broader sample.
Your viewing strategy changes according to the question.
Agentic video AI begins to do something similar.
Video Understanding Is Becoming an Information-Retrieval Problem
This is one of the bigger implications.
Long-video analysis is not only computer vision.
It increasingly resembles:
search + retrieval + reasoning + multimodal inspection.
The architecture becomes:
Video
↓
Timeline Index
↓
Agent Planning
↓
Relevant Segment Retrieval
↓
Multimodal Inspection
↓
Reasoning
↓
Answer
This looks conceptually similar to retrieval-augmented generation for documents.
Instead of retrieving:
relevant paragraphs
the system retrieves:
relevant moments.
From RAG to “Video RAG”
Traditional RAG:
Question
↓
search documents
↓
retrieve relevant chunks
↓
reason over chunks
Agentic video:
Question
↓
search timeline
↓
retrieve relevant moments
↓
inspect appropriate modalities
↓
reason over moments
The difference is that video retrieval is more complicated.
A useful unit may be:
- a transcript section
- a 10-second visual segment
- an audio interval
- several high-resolution frames
depending on the question.
That makes video retrieval inherently multimodal.
Google Reports Large Token Savings
Google reports that agentic processing can reduce token consumption by up to 88% on long-form video workloads.
Why?
Because the model may not need to load most of the video.
Imagine:
2-hour video
but the answer is contained in:
a 25-second segment.
Static processing may represent information from the entire two hours.
Agentic processing can inspect progressively until it identifies the relevant 25 seconds.
That difference becomes significant at scale.
Fewer Tokens Can Mean Lower Cost
Google also reports cost reductions of up to 66% in its evaluations.
This should not be interpreted as:
Every Gemini video request becomes 66% cheaper.
Actual cost will vary based on:
- video duration
- model
- question
- complexity
- amount of relevant content
- navigation strategy
- media resolution
A question requiring analysis of the entire timeline may offer fewer savings.
A question about one moment in a three-hour recording may benefit dramatically.
Token Efficiency Is Not Only About Cost
Reducing irrelevant context can also improve reasoning.
Imagine asking an analyst to solve a problem using:
10 relevant pages
versus:
10 relevant pages hidden inside 5,000 irrelevant pages.
More information is not always better.
Excess context can introduce noise.
Agentic video analysis can potentially improve quality because the model spends more of its working context on relevant evidence.
Google reports quality improvements of up to roughly 7% in its evaluations.
Again, that is Google’s reported benchmark result rather than a universal guarantee.
The Model Can Change Frame Rate
This is one of the most interesting capabilities.
Suppose Gemini finds that something important occurs between:
18:22
and:
18:25.
Instead of continuing at one frame per second, the system can inspect that segment with denser temporal sampling. Google says agentic mode can adjust frame rates dynamically based on the prompt and what it discovers.
That creates a hierarchy:
Broad scan
Low temporal resolution.
↓
Candidate segment
Higher temporal resolution.
↓
Critical event
Very detailed inspection.
This is similar to zooming into a map.
You do not load street-level detail for an entire country.
You zoom only where necessary.
Resolution Can Change Too
Temporal resolution is only part of the problem.
Spatial resolution matters as well.
Suppose the question is:
“What value appears on the gauge at 17:42?”
The model may need high-resolution frames to read small text.
Google’s API exposes a separate media_resolution control, allowing developers to balance visual detail against token usage. The processing mode and media-resolution settings are independent.
That creates two dimensions of optimization:
Where should I look?
and:
How closely should I look?
A Human Analogy: Scan, Then Zoom
Imagine reviewing CCTV.
You might:
- scrub through quickly
- notice suspicious movement
- rewind
- slow playback
- zoom
- replay repeatedly
That is much closer to agentic processing than fixed-rate frame ingestion.
The model is not literally watching exactly like a human, but the information strategy is similar.
Use Case 1: Finding Precise Moments
One of Google’s highlighted use cases is sub-second moment retrieval.
Potential applications include:
- sports replay
- video editing
- scientific experiments
- manufacturing
- robotics
- training footage
Example:
“Find the exact frame where the runner crosses the finish line.”
A one-frame-per-second strategy could be far too coarse.
Agentic processing can narrow to the relevant interval and inspect it more densely.
Use Case 2: Video Editing
Imagine a creator uploads a two-hour podcast and asks:
“Find every moment where the guest discusses AI regulation and identify the strongest 30-second clips.”
The model could:
- use transcript search
- locate candidate sections
- inspect surrounding video
- verify context
- return timestamps
This is significantly different from generating a generic summary.
Video AI becomes an editing assistant.
Use Case 3: Lecture and Training Analysis
Consider a six-hour training program.
The user asks:
“Where does the instructor explain partition pruning?”
The system can search transcript content first.
Then retrieve the relevant segment.
Another question:
“Show where the instructor demonstrates the configuration mistake.”
Now visual context becomes important.
A single video can support different navigation strategies depending on the question.
Use Case 4: Meetings
Meeting AI today focuses heavily on transcription.
But meetings contain more than spoken words.
There may be:
- shared screens
- diagrams
- presentation slides
- whiteboards
Imagine asking:
“When did the architecture diagram first appear, and what decision did the team make immediately afterward?”
That requires combining:
visual timeline
transcript
temporal reasoning.
Agentic video understanding is well suited to this type of cross-modal question.
Use Case 5: Industrial Inspection
Consider hours of production-line footage.
A manufacturer asks:
“Find every instance where the component entered the fixture at the wrong angle.”
Processing every frame at maximum resolution would be expensive.
An agentic system could potentially:
- search broadly
- detect candidate anomalies
- inspect suspicious intervals
- return evidence
This could make multimodal quality inspection more economically feasible.
However, safety-critical inspection requires rigorous domain-specific validation before relying on a general-purpose model.
Use Case 6: Security Video
Potential questions include:
“When did this package first appear?”
“Which person placed it there?”
“Did anyone return to the location?”
Instead of processing hours of surveillance footage uniformly, the model can navigate toward the relevant events.
But organizations need particularly strong privacy, retention, legal, and access controls for surveillance use cases.
Use Case 7: Sports Analysis
Sports video contains many events that occur very quickly.
Examples:
- ball contact
- foot placement
- boundary crossing
- tackles
- shot release
- player substitutions
Agentic inspection can help locate candidate moments and then examine them at higher temporal density.
This does not automatically make general AI suitable for officiating or other high-stakes decisions.
But it can be useful for:
- coaching
- content indexing
- highlight discovery
- post-game analysis
Use Case 8: Counting Repeated Events
Google specifically highlights improved precise counting as one of the use cases for agentic video understanding.
Questions could include:
“How many times does the technician tighten this bolt?”
“How many vehicles enter the loading area?”
“How many repetitions does the athlete complete?”
Counting temporal events can be surprisingly difficult when sampling is too sparse.
Dynamic inspection can help.
Use Case 9: Anomaly Detection
Google also highlights anomaly detection.
Suppose 59 minutes of a machine recording look normal.
One minute contains a failure sequence.
An intelligent strategy is not necessarily:
deeply process all 60 minutes.
It is:
identify signals that depart from normal → investigate those moments.
This is how agentic video begins to resemble autonomous investigation.
Use Case 10: Video Annotation
Video annotation is particularly interesting.
Traditional annotation workflows often require people to:
- watch footage
- identify objects/events
- find start/end timestamps
- assign labels
Agentic video models could potentially pre-identify:
- candidate segments
- important moments
- repeated actions
- anomalies
- likely labels
Then humans verify the annotations.
The workflow becomes:
Video
↓
AI discovers candidate events
↓
AI proposes timestamps/labels
↓
Human reviewer validates
↓
Approved annotation
This could substantially reduce the amount of video humans need to inspect manually.
Agentic Video Could Change Dataset Creation
Video datasets are expensive to create because annotation is temporally intensive.
For image annotation, one image is one unit.
For video, annotators may need to inspect:
thousands of frames per clip.
If AI can intelligently direct attention toward relevant intervals, the annotation process becomes more efficient.
A future pipeline could use:
agentic video understanding
for:
discovery
and:
specialized vision models
for:
precise annotation.
That separation could be powerful.
Discovery and Annotation Should Not Be Confused
An important distinction:
Discovery
“Something relevant happens around 12:41.”
Annotation
Object bounding box coordinates at every required frame.
General multimodal models may be excellent at discovery and semantic understanding.
Specialized computer-vision pipelines may still be better for pixel-level precision.
A mature system could combine them.
Agentic Video + Computer Vision
A future architecture could look like:
Long Video
↓
Gemini Agent
Find relevant segment
↓
Specialized Vision Model
Perform:
- detection
- tracking
- segmentation
- pose estimation
↓
Human Validation
This is often more practical than asking one model to perform every task.
Agentic Video + Audio Models
Consider detecting:
“When does the engine begin making a knocking noise?”
Visual analysis may contribute almost nothing.
The agent could instead inspect audio.
Then use video frames around the detected timestamp for context.
That illustrates why multimodal tool selection matters.
The intelligence lies partly in deciding:
Which sensor matters for this question?
Agentic Video + Transcripts
For spoken-content retrieval, transcripts are often dramatically cheaper than frames.
Question:
“What does the CEO say about revenue guidance?”
The transcript may solve 95% of the task.
Then frames can verify:
- which speaker
- which presentation slide
- surrounding visual context
The optimal workflow may therefore be:
cheap modality first
↓
expensive modality only when necessary.
That has significant cost implications.
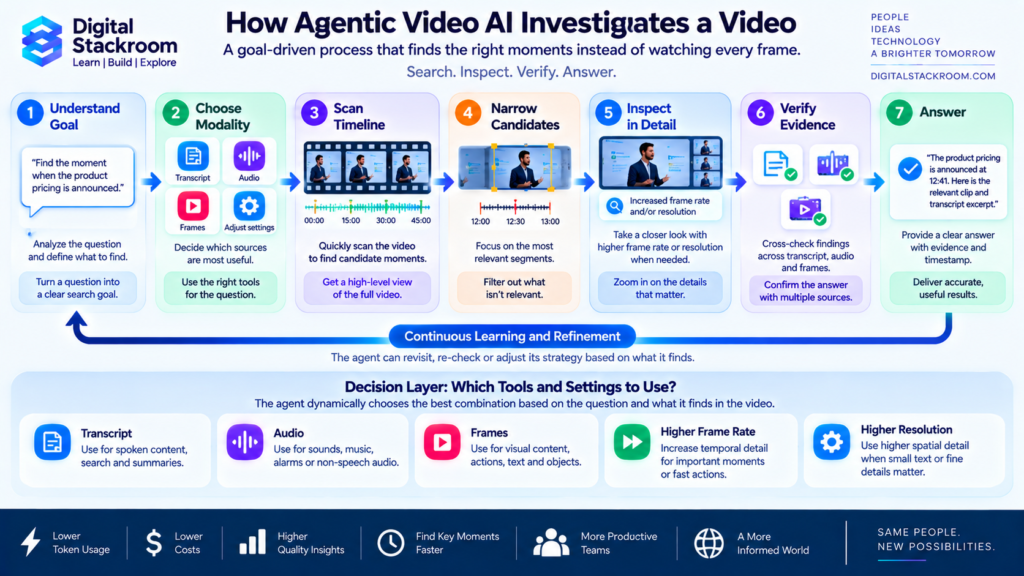
Digital Stackroom Video Investigation Loop
A useful framework is:
1. Understand the Goal
What is the user actually trying to find?
2. Choose a Search Strategy
Transcript?
Audio?
Visual timeline?
Combination?
3. Scan Broadly
Identify candidate moments.
4. Narrow the Timeline
Discard irrelevant segments.
5. Inspect Closely
Increase temporal or spatial detail.
6. Cross-Check
Compare audio, transcript, and frames where needed.
7. Answer With Evidence
Return:
- timestamp
- observation
- uncertainty
The intelligence is not only in recognizing pixels.
It is in planning the investigation.
The Agent Is Deciding What Not to Process
This may be the most important idea in the entire article.
AI progress is often discussed as:
Process more context.
Agentic video introduces another strategy:
Process less—but choose better.
That is valuable because real-world information is enormous.
No intelligent system can deeply analyze everything all the time.
Selection becomes part of intelligence.
This Principle Extends Beyond Video
The same idea appears elsewhere.
Search Agents
Do not read the entire internet.
Find relevant pages.
Data Agents
Do not query every table.
Choose relevant data.
Coding Agents
Do not load every repository file.
Inspect relevant modules.
Video Agents
Do not deeply process every frame.
Find relevant moments.
The architecture is converging around:
Plan → Retrieve → Inspect → Reason
rather than:
Load Everything → Reason.
Static Processing Still Has Advantages
Agentic should not automatically replace static video analysis.
Google’s own documentation recommends static processing in several situations, particularly short videos and workloads where frame-level coverage across the entire clip matters.
Examples:
- very short clips
- full-frame inspection
- latency-sensitive workloads
- predictable pipelines
- scenarios requiring uniform sampling
The correct processing mode depends on the question.
Why Agentic Can Be Slower for Short Videos
Agentic processing introduces overhead.
The model needs to:
- reason about where to look
- invoke internal processing tools
- retrieve segments
- inspect results
For a 20-second video, that investigation may take longer than simply processing everything.
Google specifically notes potentially increased time to first token for short clips under agentic processing.
So:
more intelligent processing
does not always mean:
faster response.
Digital Stackroom Video Processing Decision Framework
Use this practical framework.
Question 1 — Is the video short?
Yes, under roughly five minutes
→ Start by considering static.
No
→ Agentic becomes more attractive.
Google specifically recommends agentic mode for long-form video and notes static mode as appropriate for latency-sensitive short clips.
Question 2 — Does the question target a specific moment?
Example:
“When did X happen?”
→ Agentic.
Question 3 — Do you need comprehensive frame coverage?
Example:
“Inspect every frame for manufacturing defects.”
→ Static or specialized CV may be safer.
Question 4 — Is most of the video irrelevant?
Example:
Find one incident in six hours.
→ Agentic.
Question 5 — Does sub-second timing matter?
→ Agentic investigation or specialized high-frame-rate analysis.
Question 6 — Is predictable latency more important than token efficiency?
→ Static may be preferable.
Question 7 — Is the decision safety critical?
→ Use domain-specific validation regardless of processing mode.
Static vs Agentic: A Practical Decision Table
| Scenario | Recommended starting point |
|---|---|
| 30-second product demo summary | Static |
| 2-hour lecture: find one concept | Agentic |
| Find moment of equipment failure | Agentic |
| Inspect every frame of a 15-second safety test | Static/specialized CV |
| Search 5-hour meeting archive | Agentic |
| Create general summary of short video | Static |
| Extract specific spoken claim from long podcast | Agentic |
| Precise object tracking | Specialized CV + possible agentic discovery |
| Search surveillance footage for one event | Agentic, with strong governance |
| Long-form multimedia research | Agentic |
The key is not:
Which mode is technologically newer?
It is:
Which information strategy matches the task?
Current Gemini Model Support
Google launched agentic video understanding on September 1 for:
- Gemini 3.7 Flash
- Gemini 3.6 Flash
- Gemini 3.5 Flash-Lite
Google’s current video-understanding documentation additionally lists:
- Gemini 3.8 Flash
as supporting agentic processing.
This is worth mentioning because documentation can evolve after an initial product announcement.
How Developers Enable It
In the current Gemini API, developers can mark an individual video input for:
processing: "agentic"
rather than relying on the default static mode.
The API response can include special processing steps showing when the model requested additional video information.
Google documents:
processing_callprocessing_result
steps for agentic navigation.
That creates useful observability.
Developers can see that the model did not simply receive the whole video and respond.
It actively retrieved additional evidence.
Video-Agent Observability Matters
A serious production system should ideally know:
- which video was analyzed
- which segments were inspected
- which modality was used
- how many tokens were consumed
- what evidence supported the answer
Without observability, debugging becomes difficult.
Imagine a user says:
“The model missed the incident at 17:32.”
The engineering team needs to determine:
Did the agent never inspect that segment?
or:
Did it inspect the segment and misunderstand it?
Those are completely different failure modes.
New Metrics for Agentic Video Systems
Teams should monitor more than accuracy.
| Metric | Why it matters |
|---|---|
| Answer accuracy | Was the final result correct? |
| Moment-retrieval accuracy | Did it find the right segment? |
| Timestamp precision | How precisely was the event located? |
| Token usage | Was processing efficient? |
| Cost per query | Is the workload economical? |
| Time to first token | How quickly does the response begin? |
| Total investigation time | How long did the complete analysis take? |
| Segment coverage | What parts of the video were inspected? |
| Missed-event rate | What important events were skipped? |
| Human correction rate | How frequently does review change the result? |
The biggest danger is optimizing only for:
low token usage
while missing important events.
Efficiency and Recall Can Conflict
Imagine a security system that reduces token usage by 95%.
Excellent.
But if it misses 10% of security events, the optimization may be unacceptable.
Agentic video systems therefore have a fundamental trade-off:
Selective attention
versus:
comprehensive coverage.
The optimal balance depends on the business risk.
For High-Stakes Video, “Watch Less” Can Be Dangerous
Consider:
- medical procedure monitoring
- industrial safety
- autonomous systems
- security incidents
If the agent decides a segment looks unimportant and skips it, a critical event might be missed.
This is one reason general agentic video analysis should not automatically replace specialized safety systems.
In high-stakes applications, organizations may use:
continuous deterministic monitoring
plus:
agentic investigation
rather than relying on one system alone.
Use Agents to Investigate, Not Automatically Certify
A good principle:
Agentic video is excellent for finding and investigating evidence.
It should not automatically be treated as:
proof that nothing happened.
For example:
Agent says:
“I found no safety violation.”
That is different from:
“A validated safety-monitoring system proves no violation occurred.”
Absence of discovered evidence is not necessarily evidence of absence.
Privacy Becomes a Major Issue
Long-form video can contain extremely sensitive information.
Examples:
- faces
- conversations
- screens
- home environments
- location information
- children
- customer data
- confidential business information
Video AI deployments therefore need controls around:
- upload permissions
- retention
- deletion
- access
- sharing
- audit logs
- regional compliance
The convenience of AI search should not make entire video archives universally accessible.
Searchability Changes the Privacy Risk
This is subtle.
A company might already possess:
10,000 hours of internal video.
Humans technically could review it.
But that is difficult.
An AI agent makes it searchable.
Now an employee could potentially ask:
“Find every video where employee X discussed project Y.”
The data did not change.
Its accessibility changed dramatically.
That is why AI governance needs to consider not only:
What data exists?
but:
What questions does AI make practical to ask?
Video Permissions May Need to Become More Granular
Traditional access:
User can view this recording.
Agent-era question:
Can the user ask AI to analyze this recording together with 500 other recordings?
Those are not necessarily equivalent permissions.
Large-scale AI retrieval can expose patterns that individual-file access did not practically reveal before.
Organizations may eventually need distinct controls around:
- viewing
- searching
- bulk analysis
- cross-video aggregation
Copyright and Video Analysis
Developers also need to consider the rights associated with video inputs.
Being technically able to upload and analyze a video does not automatically mean an organization has permission to:
- reproduce it
- redistribute it
- train on it
- publish extracted clips
For business deployments, video provenance and usage rights should be part of the ingestion workflow.
Long Videos Create Context-Window Pressure
Google says models with a one-million-token context window can process long videos, but duration limits and token use depend on resolution and processing strategy.
The important point is that video consumes context quickly.
Agentic processing changes the economics because it avoids filling the context window with information that may never matter.
This could make longer-duration analysis much more practical.
Agentic Video and Memory Are Different Problems
Suppose a model analyzes a three-hour conference.
It finds:
- keynote
- product announcement
- pricing discussion
Now you ask a follow-up:
“Compare the pricing announcement with what the CEO said earlier.”
The system needs to preserve enough prior video context to answer.
Google’s current API supports multi-turn video conversations, with the handling differing between stateful and stateless modes.
This shows that video intelligence involves two distinct problems:
finding information
and:
remembering useful findings across turns.
The Future Video Agent May Build Its Own Index
A more advanced architecture could perform an initial pass and build:
- scene boundaries
- transcript index
- object index
- speaker index
- event summaries
- timestamps
Future questions could search that index before reopening raw footage.
Conceptually:
Video
↓
Multimodal Index
↓
Agent Search
↓
Targeted Reinspection
↓
Answer
That could dramatically reduce repeated processing.
Video Understanding Could Become a Platform Capability
Today companies often build separate systems for:
- transcription
- scene detection
- object detection
- content search
- summarization
Agentic multimodal models could increasingly act as an orchestration layer across those functions.
A company might expose one interface:
“Find the relevant video evidence.”
Behind the scenes, the system decides which capabilities to invoke.
This mirrors what is happening elsewhere in agentic computing.
The Interface Could Simply Become a Question
Imagine a media archive containing 100,000 hours of video.
Traditional interface:
- folders
- filenames
- metadata filters
- date ranges
Future interface:
“Find all product demos where the presenter discusses offline mode and show me the relevant clips.”
The agent determines:
- which files matter
- where inside them to look
- which modality contains evidence
The unit of interaction moves from:
video file
to:
question.
What This Means for Video Editors
Video editors could gain an intelligent search assistant.
Instead of manually scrubbing footage:
“Find the cleanest shot of the speaker entering the stage.”
“Find every time the product dashboard appears.”
“Find the strongest audience reaction.”
The agent can propose candidate timestamps.
The editor remains responsible for creative judgment.
AI reduces search time.
What This Means for Data Teams
Organizations will increasingly treat video as queryable data.
That means data architectures may need:
- media storage
- metadata
- permissions
- indexes
- annotations
- embeddings
- lineage
- retention
The distinction between:
media platform
and:
data platform
begins to blur.
What This Means for AI Engineers
Video systems require skills beyond prompting.
Engineers need to think about:
- media ingestion
- codecs
- video duration
- frame rate
- temporal resolution
- audio
- context windows
- token cost
- retrieval strategy
- evaluation datasets
The question becomes:
How do we give the model enough evidence without wasting computation?
That is a systems problem.
What This Means for Annotation Teams
Annotation workflows could shift from:
humans search + humans label
to:
AI searches + AI proposes + humans verify.
That can improve throughput.
But verification remains essential because incorrect automatically generated annotations can contaminate training data.
A high-volume incorrect annotation pipeline is worse than a slower accurate one.
Human-in-the-Loop Video Annotation
A strong workflow could be:
Raw video
↓
Agentic discovery
↓
Candidate event
↓
Specialized annotation model
↓
Human QC
↓
Approved label
↓
Training dataset
This architecture uses each component where it is strongest.
The Cost Equation for Video AI
A useful simplified model is:
Total Video Analysis Cost
≈
Video Information Loaded
×
Model Cost
Reasoning/Navigation Cost
Agentic processing attempts to reduce:
information loaded
even if it introduces some:
navigation reasoning.
That trade can be highly favorable for long-form content.
Cheap Search Before Expensive Inspection
This principle is likely to become common.
Start with:
transcript
if sufficient.
Then:
low-resolution frames.
Then:
high temporal sampling.
Then:
high resolution
only when needed.
The hierarchy becomes:
cheapest evidence first
↓
more expensive evidence when uncertainty remains.
This is economically elegant.
Not Every Question Needs Video at All
Suppose someone asks:
“What are the five topics discussed in this podcast?”
If the podcast transcript is available and accurate, the answer may require no visual processing.
A smart system should recognize that.
The best video AI may sometimes decide:
I don’t need to watch the video.
That is exactly the kind of efficiency agentic systems enable.
Video-Agent Evaluation Is Hard
Text evaluation often asks:
Is the answer correct?
Video adds:
- Did it find the correct moment?
- Was the timestamp accurate?
- Did it miss something nearby?
- Was visual evidence necessary?
- Did the transcript conflict with the frames?
- Did it inspect enough of the timeline?
Organizations need evaluation datasets built around real video workloads.
Build a Video Golden Dataset
Before deploying an agentic video system, collect test videos containing known answers.
Examples:
Moment Finding
Known event at:
13:42.38
Counting
Known count:
17
Anomaly
Known abnormal interval:
41:20–41:47
Spoken Claim
Known transcript section.
Visual Detail
Known value displayed on screen.
Then evaluate the model repeatedly.
Do not rely only on impressive demos.
Accuracy Needs Multiple Dimensions
A model might correctly say:
“The incident occurs around minute 42.”
But if the application requires frame-level editing, that may be insufficient.
Define accuracy according to your workflow.
Possible metrics:
- answer accuracy
- timestamp error
- count error
- event recall
- event precision
- temporal IoU
- human review time
Evaluation needs to reflect business requirements.
Where Agentic Video Should Not Be the Only System
Be cautious in:
- medical diagnosis
- legal evidence analysis
- autonomous driving
- industrial safety shutdown
- biometric surveillance
- critical security monitoring
Agentic models can assist investigation.
They should not automatically become the sole authority without appropriate validation.
The Bigger Shift: AI Is Learning How to Allocate Attention
For years, one direction of AI progress was straightforward:
larger context windows.
Give the model more information.
Agentic video highlights a complementary strategy:
better attention allocation.
Do not ask:
How much context can the model ingest?
Ask:
How effectively can the model decide what context it needs?
That may be a more scalable path.
Bigger Context Is Not the Same as Better Context
Imagine giving an AI:
one million tokens
of irrelevant information.
That is technically impressive.
But not necessarily useful.
An intelligent agent needs to identify:
the smallest amount of evidence necessary to make a reliable decision.
Agentic video makes that principle visible because the raw information volume is so large.
The Same Architecture Could Expand to Other Media
Consider:
Audio
Search a 10-hour recording and listen closely only around relevant sections.
Documents
Open only relevant pages.
Databases
Query only relevant tables.
Code
Inspect only relevant dependencies.
Video
Watch only relevant moments.
The common pattern is:
Goal
↓
Plan
↓
Retrieve
↓
Inspect
↓
Reason
This may become one of the defining architectures of agentic AI.
The Future AI System May Be an Investigator, Not a Reader
Traditional AI:
Give me information and I will reason over it.
Agentic AI:
Give me access to the information and a goal. I will decide what evidence I need.
That is a much larger capability shift.
It changes models from:
content processors
into:
information investigators.
Gemini’s agentic video understanding is one concrete example of that broader trend.
Frequently Asked Questions
What is Gemini agentic video understanding?
Gemini agentic video understanding is a Gemini video-processing mode where the model dynamically navigates the video timeline and selectively loads transcripts, frames, or audio based on the question rather than ingesting the entire video at a fixed sampling rate.
When did Google launch agentic video understanding?
Google announced the capability on September 1, 2026.
Which Gemini models support agentic video understanding?
At launch, Google listed Gemini 3.7 Flash, 3.6 Flash, and 3.5 Flash-Lite. Current Gemini documentation also lists Gemini 3.8 Flash.
How is agentic video different from static processing?
Static processing samples video at a fixed frame rate—1 FPS by default—and places those frames into context. Agentic mode dynamically navigates the timeline and loads only the transcript, audio, or frames needed for the question.
Does agentic video use fewer tokens?
Google reports up to 88% lower token consumption for long-form content in its evaluations. Actual savings will depend on the video and query.
Does it reduce cost?
Google reports cost reductions of up to 66% in its published evaluations. This should not be interpreted as a guaranteed reduction for every request.
Does agentic processing improve accuracy?
Google reports quality improvements of up to approximately 7% in its evaluations, particularly for demanding long-form analysis tasks.
Can Gemini search YouTube videos?
Google’s launch announcement says agentic video understanding can be used with uploaded videos and YouTube videos through supported Gemini interfaces.
Can the model change the video frame rate while analyzing?
Yes. Google’s current documentation says agentic processing can dynamically adjust frame rate and resolution while exploring the video based on the prompt.
Is static video processing still available?
Yes. Static remains the default processing mode and continues to be useful for short clips, latency-sensitive requests, and cases requiring consistent frame-level coverage.
Is agentic processing always faster?
No. Google notes that agentic processing can increase time to first token on shorter videos because the system performs navigation reasoning and additional tool interactions before producing the final answer.
Can agentic video be used for video annotation?
It can potentially help locate relevant events, timestamps, anomalies, or candidate segments. For precise bounding boxes, segmentation, or frame-level tracking, specialized computer-vision models and human verification may still be appropriate.
Final Thoughts
The most important thing about Gemini agentic video understanding is not simply that Gemini can analyze video.
Multimodal AI could already do that.
The important shift is that the model can increasingly decide:
What should I look at?
Instead of treating every second equally, it can:
Understand the question
↓
Search the timeline
↓
Choose the relevant modality
↓
Inspect candidate moments
↓
Increase detail when necessary
↓
Verify
↓
Answer
That transforms video understanding from:
content ingestion
into:
active investigation.
It also reveals something broader about the future of AI.
The world contains far more information than any model should process deeply all the time.
The most capable systems therefore may not simply have the largest context windows.
They may be the systems best able to determine:
Which context is actually worth using?
For video, that could mean ignoring 99 minutes and closely analyzing one.
For databases, it could mean querying three relevant tables instead of scanning fifty.
For code, it could mean tracing only the dependencies related to a bug.
For documents, it could mean opening only the pages containing supporting evidence.
The architecture is converging on:
Goal
→ Plan
→ Retrieve
→ Inspect
→ Verify
→ Answer
Google’s agentic video capability is therefore interesting for more than video developers.
It demonstrates a larger change in how AI systems may handle enormous information environments.
The next generation of AI may not win by processing everything.
It may win by learning what not to process.
And for video—a medium containing millions of potential visual moments—that difference could completely change the economics and usefulness of AI analysis.