GitHub has completed one of the most interesting AI-assisted software migrations yet.
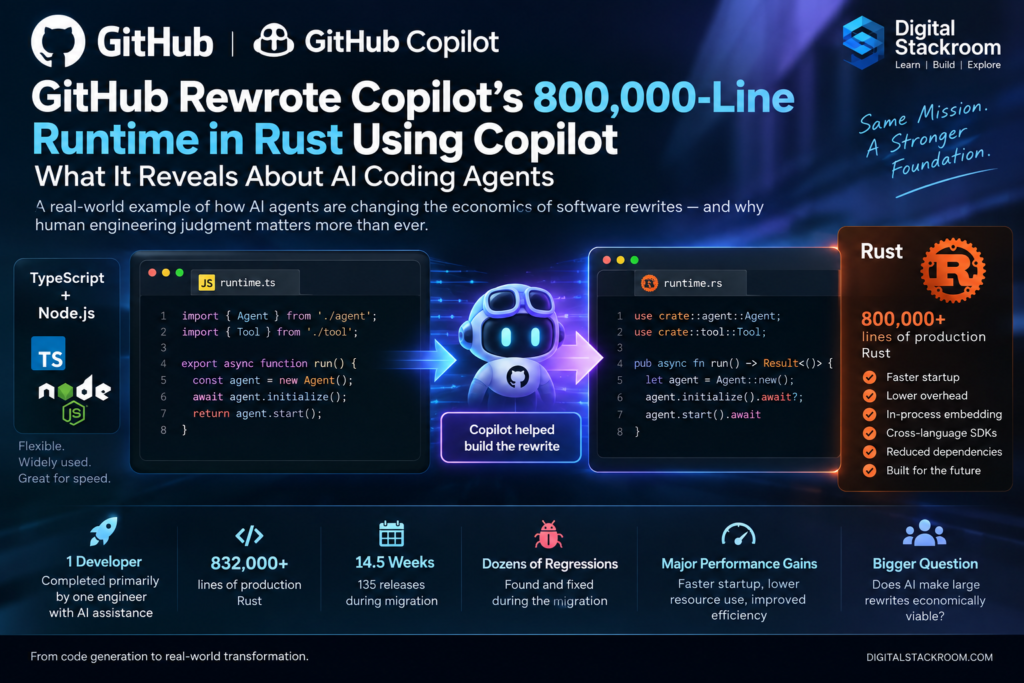
The company rewrote the runtime behind major parts of GitHub Copilot from TypeScript and Node.js into more than 800,000 lines of production Rust, while using GitHub Copilot itself extensively during the migration.
According to GitHub, AI agents wrote most of the new implementation. The migration landed incrementally rather than through one massive replacement, and the resulting Rust runtime now powers systems behind the Copilot CLI, Copilot app, SDK and other Microsoft and GitHub products.
The headline sounds simple:
AI helped rewrite a massive software system.
But the engineering lesson is much more interesting.
The project raises questions that every software organization will increasingly need to answer:
- Does AI make large rewrites economically viable?
- Can one engineer now undertake migrations that once required entire teams?
- Does generating code faster reduce project risk?
- Are traditional “never rewrite from scratch” rules becoming outdated?
- What happens when AI writes hundreds of thousands of lines but behavioral correctness still has to be proved?
The GitHub Copilot Rust rewrite suggests that AI coding agents may dramatically change the economics of software migration.
It does not eliminate the hard parts of software engineering.
In some ways, it makes them more important.
Table of Contents
The Short Version
GitHub’s Copilot agent runtime was originally implemented primarily in TypeScript on Node.js and V8.
GitHub wanted a runtime that could be:
- embedded more cleanly inside other applications
- started with less overhead
- used across several programming-language SDKs
- operated with fewer runtime dependencies
- optimized for predictable performance
- supported with a stronger native-toolchain security posture
GitHub chose Rust for those requirements.
During the migration, roughly 430,000 lines of production TypeScript ultimately passed through the porting process. By August 21, the new runtime contained approximately 832,000 lines of production Rust, plus hundreds of thousands of lines of Rust and end-to-end tests.
But the most important result was not the line count.
It was that GitHub says a project that previously might have required an entire team for a year or two became feasible for primarily one engineer working over several months with AI-agent assistance, while the wider team continued building new features. That is GitHub’s assessment of this particular project, not a general benchmark for every codebase.
That changes the economics of a rewrite.
What Exactly Did GitHub Rewrite?
The system at the center of the migration is the Copilot agent runtime.
Think of it as part of the machinery that allows GitHub Copilot to:
- manage agent sessions
- call tools
- maintain context
- interact with models
- persist state
- coordinate actions
- handle events
- work across different host applications
GitHub says this runtime underpins a growing range of products and integrations, rather than being limited to one standalone CLI.
That matters because this was not an isolated internal utility.
It was a live production runtime with many downstream consumers.
Changing its implementation therefore created a difficult requirement:
GitHub needed to rewrite the engine while the car was still moving.
Why Move From TypeScript to Rust?
The story is sometimes summarized as:
Rust is faster than TypeScript.
That is too simplistic.
GitHub outlined several architectural reasons for the migration.
The runtime needed to work cleanly across multiple host environments and language SDKs while minimizing process boundaries and unnecessary runtime dependencies. Rust also gave GitHub a native binary and an interoperability model suitable for embedding through C-compatible interfaces.
Performance mattered, but so did architecture.
The key goals included:
Lower startup overhead
An agent runtime may be created frequently. Startup cost therefore matters more than it would for a permanently running server.
Predictable resource usage
Desktop applications and embedded developer tools care about memory and runtime overhead.
In-process embedding
Instead of always launching a separate Node.js process, a native runtime can potentially be loaded directly by the host.
Cross-language interoperability
The Copilot SDK supports several languages, so a native runtime needed a stable way to communicate with all of them.
Reduced dependency surface
A smaller runtime dependency chain can simplify deployment and reduce parts of the software supply-chain surface.
These requirements made Rust attractive for GitHub’s use case.
But GitHub explicitly cautioned that this does not mean every large TypeScript application should be rewritten in Rust.
That distinction is important.
The GitHub Copilot Rust Rewrite Was Much Bigger Than Expected
GitHub initially estimated the runtime at around 130,000 lines of TypeScript.
That estimate became misleading as the migration progressed.
Why?
Because the system itself was continuing to evolve.
While the migration was happening:
- new TypeScript code continued arriving
- runtime responsibilities were being reorganized
- functionality was moving out of other layers
- unrelated development continued in parallel
GitHub eventually estimated that approximately 430,000 production TypeScript lines passed through the migration.
At completion, the production Rust implementation exceeded 830,000 lines.
This is a good reminder that:
Code migration is rarely a simple one-to-one translation exercise.
The target architecture often changes while the migration is happening.
AI Did Not Simply Translate TypeScript Into Rust
This distinction matters enormously.
The easiest mental model would be:
TypeScript file → AI translation → Rust file
That was not the real project.
A language migration of this size also requires replacing:
- libraries
- runtime behavior
- state-management approaches
- concurrency patterns
- serialization mechanisms
- process communication
- error handling
- platform abstractions
GitHub notes that some Node.js packages had straightforward Rust equivalents.
Others required multiple Rust crates.
Some capabilities had no satisfactory direct replacement and had to be implemented specifically for the migration.
That makes the project a useful example of a broader principle:
An AI-assisted rewrite is still an architecture project.
How GitHub Avoided a Big-Bang Rewrite
One of the strongest decisions in the project was not AI-related at all.
GitHub migrated incrementally.
Instead of building an entirely separate Rust implementation for months and switching everything over one day, components were ported gradually into the production codebase.
GitHub reports that the roughly fourteen-and-a-half-week migration window included 135 releases, with new pieces shipping continuously.
This reduced one of the biggest risks of rewrites:
the giant final cutover.
Consider the alternative.
A team creates:
runtime-v2-rust
while production continues evolving in:
runtime-v1-typescript
After six months:
- features have diverged
- bug fixes differ
- APIs have changed
- testing environments differ
Then the organization attempts one enormous migration.
That is where rewrites become dangerous.
GitHub instead kept the migration close to production.
The Migration Pattern: Move From the Leaves Inward
GitHub did not begin with the hardest stateful components.
It started with relatively isolated logic.
A useful migration progression looks like this:
Pure functions
↓
Utilities
↓
Filesystem and supporting operations
↓
State ownership
↓
Tools and model clients
↓
Agent orchestration
↓
Public runtime entry points
This is an important pattern for engineering teams considering AI-assisted migrations.
Start where behavior is:
- deterministic
- heavily tested
- easy to compare
- minimally stateful
Then use what you learn to tackle harder components.
AI can accelerate implementation.
But sequencing reduces risk.
The Most Important Sentence in GitHub’s Story
One sentence from the engineering write-up summarizes the real lesson:
Porting code is easy. Making it correct is hard.
That principle matters far beyond Rust.
Modern AI coding agents can generate enormous volumes of plausible software.
The limiting factor increasingly becomes:
Can we prove that the generated software behaves correctly?
GitHub says that by September 14 it had traced and fixed dozens of known regressions associated with the migration.
Some never reached stable users.
Some appeared during prereleases.
Others reached stable releases before being identified.
That should temper any simplistic interpretation of the project.
The Five Kinds of Regression That Matter
GitHub grouped migration bugs into recurring categories. The categories themselves reveal where AI-assisted rewrites become difficult.
1. Incomplete Migration
A feature may look successfully translated while some edge behavior is missing.
This is especially dangerous when the original code has years of accumulated exceptions.
AI often understands:
what the normal path does
more easily than:
why this strange line was added three years ago.
2. State and Lifetime Problems
Rust requires developers to reason explicitly about ownership and lifetime.
A Node.js implementation may rely on garbage collection and object lifecycles that do not translate directly.
Changing languages can therefore expose hidden architectural assumptions.
3. Behavioral Contract Mismatches
Two implementations can look equivalent while behaving differently at the boundaries.
Examples:
- error ordering
- timeout behavior
- empty values
- cancellation
- event sequencing
- serialization
The code may compile.
Tests may pass.
The application can still behave differently.
4. Host-Boundary Problems
The runtime interacts with multiple host environments.
That means migration bugs can appear not inside the core algorithm but at:
runtime ↔ application
runtime ↔ SDK
runtime ↔ operating system
boundaries.
5. Incorrect Test Oracles
This may be the most subtle category.
A test only proves something useful if the expected answer is actually correct.
If both:
- generated implementation
- generated test expectation
contain the same mistaken assumption, tests can provide false confidence.
That leads directly to one of the biggest lessons of AI coding.
AI Can Generate Tests, But Humans Still Need to Define Correctness
Suppose an agent rewrites a component.
Then another agent writes the test.
You now have:
AI-generated implementation
tested by:
AI-generated expectation
That can be useful.
But it creates a danger.
Where did the definition of correct behavior come from?
For large migrations, the strongest test oracle is often:
the existing production behavior.
That suggests a powerful pattern:
Differential testing
Run identical inputs through:
Old implementation
and
New implementation
Then compare:
- outputs
- state changes
- events
- errors
- performance
- resource behavior
This is particularly valuable for AI-assisted rewrites.
AI Coding Agents Change the Cost of Migration
This may be the most consequential part of GitHub’s experience.
Historically, organizations avoided many rewrites because the opportunity cost was enormous.
Imagine a project requiring:
8 engineers × 18 months
Those engineers are not building new customer features.
That alone can kill the proposal.
AI agents change that calculation.
If agents can automate large amounts of:
- translation
- boilerplate
- test creation
- mechanical refactoring
- dependency conversion
- repetitive cleanup
then the implementation cost of migration falls.
The project may move from:
economically unrealistic
to:
worth evaluating.
That does not mean every rewrite becomes worthwhile.
It means more rewrites enter the feasible decision space.
Does This Mean “Never Rewrite Software” Is Outdated?
For decades, engineering culture has warned against large rewrites.
There are good reasons.
Rewrites often underestimate:
- hidden requirements
- accumulated bug fixes
- operational knowledge
- edge cases
- integration complexity
- migration cost
Teams see ugly old code and assume:
“We could rebuild this much cleaner.”
They discover later that much of the ugliness encoded real business behavior.
AI does not remove that problem.
But AI changes one variable:
implementation cost.
Previously:
Rewrite value < engineering cost + migration risk
With strong coding agents:
engineering cost ↓
The risk may remain.
That means some projects that previously failed the business case may now pass it.
The New Rewrite Equation
Engineering leaders can think about an AI-assisted rewrite using five factors.
1. Implementation Cost
How much coding work can agents genuinely automate?
2. Validation Cost
How expensive is proving behavioral equivalence?
3. Migration Risk
What happens if subtle differences reach production?
4. Architectural Benefit
What does the new implementation unlock?
5. Opportunity Cost
What would the engineering team build instead?
Then evaluate:
Rewrite Value = Architectural Benefit + Operational Benefit − Implementation Cost − Validation Cost − Migration Risk − Opportunity Cost
AI primarily reduces one part:
implementation cost.
It may also reduce parts of validation cost.
It does not make migration risk disappear.
Why GitHub’s Testing Investment Matters More Than the 800,000 Lines
The headline metric is:
800,000+ lines of Rust.
But line count is a poor measure of software value.
A more meaningful detail is the testing infrastructure surrounding the migration.
GitHub reported hundreds of thousands of lines of Rust unit tests along with a large existing end-to-end test suite spanning the runtime and SDK ecosystem.
That is what makes an AI-generated migration believable.
Without strong validation, generating 800,000 lines quickly would simply create:
800,000 lines that must now be trusted somehow.
Tests turn generated code into something that can be evaluated.
AI Coding Productivity Is Moving From Lines to Verified Change
Historically, developer productivity was sometimes approximated using:
- lines of code
- commits
- pull requests
- tickets
AI makes those metrics increasingly meaningless.
An agent can generate thousands of lines quickly.
That does not mean thousands of lines of value were created.
A better measure is:
How much verified behavior can an engineering system safely change per unit of time?
That includes:
- implementation
- testing
- review
- deployment
- observability
- rollback
This is where AI coding may ultimately matter most.
Not:
more code
but:
faster verified change.
The Performance Results Were Significant
GitHub also reported substantial runtime-performance improvements after the migration.
In its controlled tests, operations such as startup, session handling and repeated lifecycle creation became considerably faster, particularly when the Rust runtime ran in-process rather than behind an extra process boundary. GitHub cautions that other changes occurred during the same period, so the measurements should not be interpreted as a pure Rust-vs-TypeScript benchmark.
That caveat matters.
A migration should not claim:
Rust is X times faster than TypeScript
based on this project.
The architectural changes included more than simply swapping languages.
Why In-Process Execution Matters for AI Agents
Traditional application performance often focuses on server throughput.
Agent runtimes have different characteristics.
An agent may repeatedly:
- start sessions
- invoke tools
- persist context
- resume conversations
- communicate with host applications
Process startup and IPC overhead can therefore matter significantly.
A native runtime embedded directly into another application reduces some of those boundaries.
That is one reason GitHub’s migration was architectural, not merely linguistic.
What AI Agents Actually Contributed
It is useful to separate what AI was good at from what remained difficult.
AI was especially useful for:
- translating repetitive implementation patterns
- generating Rust scaffolding
- converting tests
- handling mechanical changes
- writing adapters
- updating APIs
- producing repetitive interop code
- accelerating iteration
Humans remained essential for:
- choosing the architecture
- sequencing the migration
- defining behavioral expectations
- evaluating regressions
- making trade-offs
- reviewing security implications
- deciding when results were production-ready
This division of labor is likely to become common.
One Engineer Does Not Mean One-Person Engineering
GitHub describes the migration as being completed primarily by a single developer with AI support while the larger team continued product development.
That is impressive.
But organizations should interpret it carefully.
The developer still operated inside an ecosystem containing:
- existing engineers
- reviewers
- CI/CD
- tests
- production telemetry
- users
- code review
- organizational knowledge
The lesson is not:
one engineer + AI replaces an engineering organization.
A better interpretation is:
A strong engineering system can dramatically amplify an individual engineer using agents.
AI Amplification Depends on Repository Quality
Imagine two repositories.
Repository A
- comprehensive tests
- clear build instructions
- deterministic CI
- typed APIs
- good documentation
- reproducible development environment
Repository B
- little test coverage
- undocumented behavior
- fragile builds
- manual deployments
- inconsistent patterns
- unclear ownership
Which repository will AI agents migrate more safely?
Almost certainly Repository A.
This suggests an emerging competitive advantage:
AI-readiness of the codebase.
What Makes a Repository AI-Ready?
Engineering teams preparing for agentic development should invest in:
Strong automated tests
Agents need rapid feedback.
Deterministic builds
The agent must distinguish its mistake from infrastructure instability.
Repository instructions
Coding conventions and architectural boundaries should be explicit.
Small interfaces
Clear component boundaries make migration safer.
Fast CI
An agent that waits 40 minutes for every validation loop loses much of its advantage.
Observability
Production behavior must be measurable after deployment.
Reversible deployments
Agent velocity is dangerous without rollback.
These investments benefit humans too.
Should Companies Start Rewriting Everything?
No.
The GitHub Copilot Rust rewrite is an exceptional case with unusually strong reasons for migration.
A rewrite may be justified when several conditions align.
Strong candidates
Systems with:
- clear architectural limitations
- strong automated tests
- measurable runtime bottlenecks
- stable behavioral contracts
- costly legacy dependencies
- clear target architecture
- high long-term maintenance value
Weak candidates
Systems where the motivation is simply:
“The code looks old.”
or:
“Rust is fashionable.”
or:
“AI can generate it quickly.”
The existence of cheap code generation is not a business case.
The AI-Assisted Rewrite Decision Framework
Before approving a rewrite, ask these questions.
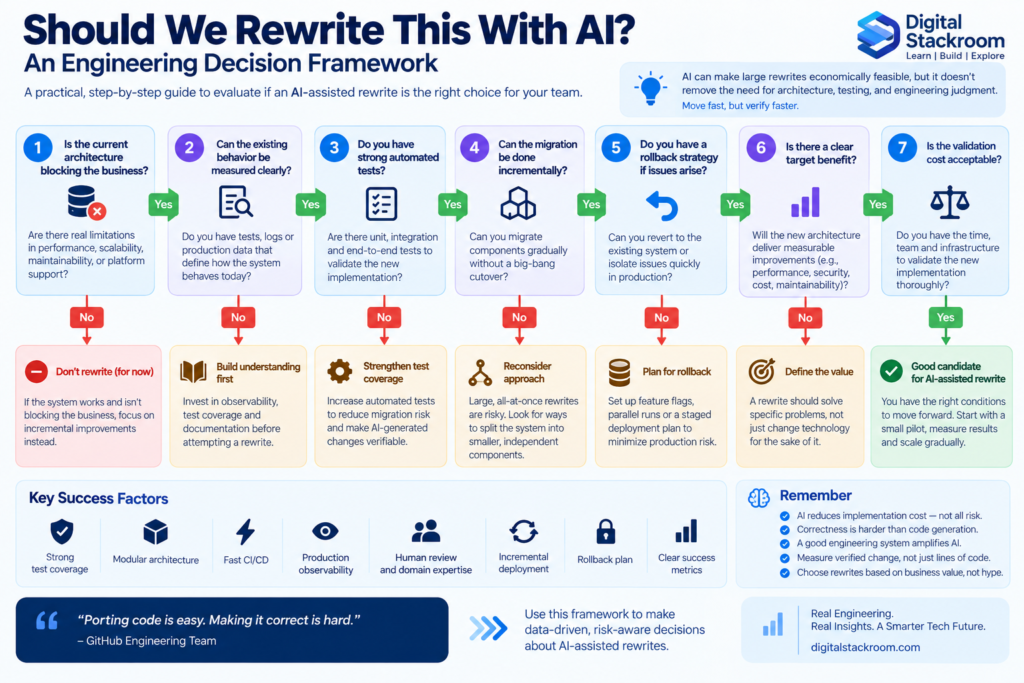
1. Is the existing architecture blocking the business?
Examples:
- unacceptable performance
- deployment limitations
- platform incompatibility
- reliability constraints
If not, incremental improvement may be better.
2. Can existing behavior be measured?
If nobody knows exactly what the legacy system does, rewriting it is dangerous.
3. Is there adequate test coverage?
AI-generated code without reliable validation increases risk.
4. Can the migration happen incrementally?
Prefer:
component migration
over:
six-month hidden branch + giant cutover.
5. Is rollback possible?
Every migrated component should have a safe recovery path.
6. Is the target architecture clearly superior?
The new system should solve specific problems.
7. What is the validation cost?
Generating code may become cheap while proving it correct remains expensive.
A Practical AI Rewrite Workflow
An organization could adapt GitHub’s approach into the following process.
Phase 1 — Measure
Document:
- current architecture
- performance
- tests
- dependencies
- known behavior
Phase 2 — Pilot
Select a low-risk component.
Ask the coding agent to migrate it.
Compare old and new behavior.
Phase 3 — Build Migration Infrastructure
Create:
- CI rules
- differential tests
- adapters
- compatibility interfaces
- performance benchmarks
Phase 4 — Move Incrementally
Migrate related groups of functionality.
Keep changes small enough to review.
Phase 5 — Ship Continuously
Expose new components gradually.
Monitor telemetry.
Phase 6 — Remove Compatibility Layers
Once all callers use the new implementation, remove temporary bridges.
Phase 7 — Simplify
AI-assisted migrations can generate mechanically correct but unnecessarily complex code.
Perform a final architecture cleanup.
What Engineering Leaders Should Measure
Do not measure the rewrite primarily by lines converted.
Track:
| Metric | Why it matters |
|---|---|
| Migrated behavior | Measures actual progress |
| Regression count | Measures migration quality |
| Test coverage | Measures confidence |
| Performance | Confirms architectural benefit |
| Memory/resource use | Measures runtime efficiency |
| Pull-request review time | Shows human validation cost |
| Agent iterations | Shows automation efficiency |
| Production incidents | Measures real risk |
| Rollback frequency | Exposes unstable components |
| Developer maintenance time | Shows long-term value |
The best migration is not the one producing the most code.
It is the one improving the system while maintaining correctness.
What This Means for Junior Developers
Stories like this inevitably create anxiety:
If an AI agent can write hundreds of thousands of lines, why hire developers?
Because generating code is becoming only one portion of engineering.
The skills becoming more valuable include:
- understanding systems
- designing interfaces
- defining requirements
- writing tests
- evaluating AI output
- debugging
- security
- architecture
- production operations
Junior developers should therefore learn both:
how to code
and:
how to verify code created by agents.
That second skill will become increasingly important.
What This Means for Senior Engineers
Senior engineers may see even more leverage.
Instead of personally implementing every repetitive migration detail, they can spend more time on:
- architecture
- migration sequencing
- constraints
- validation strategy
- review
- performance
- risk
The agent becomes an implementation multiplier.
That makes engineering judgment more—not less—valuable.
What This Means for Engineering Managers
Managers may need to rethink project estimation.
A task that historically required:
10 engineers for 12 months
cannot automatically be re-estimated as:
1 engineer for 1 month with AI.
But historical estimates will increasingly need adjustment when large portions of work are:
- repetitive
- testable
- well specified
- suitable for agents
Project estimation may need a new factor:
agentability.
What Is Agentability?
A task has high agentability when:
- expected behavior is clear
- tests exist
- feedback is fast
- interfaces are explicit
- mistakes are reversible
A task has low agentability when:
- requirements are ambiguous
- behavior is undocumented
- feedback comes months later
- errors have severe consequences
- success depends on social or business context
Large code migrations can surprisingly have high agentability when the old implementation provides a strong reference.
The Paradox: Legacy Code May Become Easier to Modernize
Legacy modernization has traditionally been expensive because organizations must manually reproduce large amounts of existing behavior.
But legacy software also contains something agents can use:
a working specification encoded in code.
If:
- tests exist
- behavior can be observed
- inputs and outputs can be compared
then an agent can use the existing system as a reference.
This could make AI especially valuable in:
- language migrations
- framework upgrades
- dependency replacement
- API modernization
- monolith decomposition
- infrastructure conversion
That may become one of the largest enterprise applications of coding agents.
But Legacy Modernization Can Still Fail Spectacularly
AI increases implementation speed.
That can also increase failure speed.
Imagine an agent migrating:
10 components per week
while a human team can deeply review only:
2 components per week.
A validation backlog develops.
Velocity becomes dangerous.
The constraint shifts from:
How quickly can we write the code?
to:
How quickly can we establish confidence?
That is the central engineering challenge of agentic development.
What GitHub’s Regressions Tell Us
The dozens of known regressions are not evidence that the project failed.
They are evidence that migrations remain hard.
More importantly, GitHub documented them publicly.
That reveals an important maturity principle:
Expect regressions and design the migration system to detect them quickly.
The wrong goal is:
zero migration defects.
A more realistic operational goal is:
small blast radius + fast detection + fast recovery.
The Real Bottleneck Is Moving Up the Stack
Software engineering has historically spent enormous time on implementation.
AI reduces parts of that burden.
The bottleneck moves upward:
Before
Architecture
↓
Implementation ← expensive
↓
Testing
↓
Deployment
With coding agents
Architecture
↓
Implementation ← much cheaper
↓
Testing & verification ← new bottleneck
↓
Deployment
This is why organizations investing only in coding assistants may be disappointed.
They also need better:
- tests
- CI
- observability
- code review
- deployment automation
Could AI Create More Software Rewrites?
Probably.
Some projects previously rejected because of engineering cost may become economically viable.
We may see more:
- Java → Kotlin
- JavaScript → TypeScript
- Python → Rust
- legacy framework → modern framework
- on-premises → cloud-native
- monolith → modular architecture
But the successful migrations will not be those generating code fastest.
They will be those with the strongest validation systems.
GitHub’s Project May Be a Preview of “Software Refactoring at Industrial Scale”
Traditional refactoring usually happens incrementally.
AI agents could potentially enable a new category:
large-scale continuous transformation.
Imagine an organization continuously modernizing:
- old APIs
- frameworks
- dependencies
- languages
- security patterns
without pausing product development.
That is potentially more important than autocomplete.
The coding agent becomes:
migration infrastructure.
Frequently Asked Questions
Did GitHub really rewrite Copilot in Rust?
GitHub rewrote the Copilot agent runtime, not every part of GitHub Copilot.
GitHub reports that the new runtime contains more than 800,000 lines of production Rust.
Did Copilot write all 800,000 lines?
No.
GitHub says AI agents wrote most of the code, but engineers designed, guided, tested, reviewed and debugged the migration.
How long did the migration take?
GitHub describes the main porting window as roughly fourteen and a half weeks, with work taking place over several months.
Why did GitHub choose Rust?
GitHub cited requirements including lower overhead, in-process embedding, interoperability, performance, reliability and reduced dependency concerns. It explicitly says the choice was specific to its requirements rather than a recommendation that every TypeScript system move to Rust.
Were there bugs after the migration?
Yes.
GitHub says dozens of known migration regressions had been identified and fixed by September 14, including correctness and some performance issues.
Was the migration done all at once?
No.
GitHub used an incremental migration strategy and continuously shipped portions of the new implementation.
Does this prove AI can replace software engineers?
No.
The project demonstrates that coding agents can greatly amplify implementation capacity in a well-engineered environment. Architecture, testing, review, debugging, deployment and operational judgment remained essential.
Should companies now rewrite legacy systems with AI?
Only when there is a clear architectural or business benefit and sufficient validation infrastructure.
AI changes the cost equation.
It does not remove rewrite risk.
Final Thoughts
The most important lesson from the GitHub Copilot Rust rewrite is not that an AI agent can produce 800,000 lines of code.
Lines of code are becoming cheap.
The important achievement is that GitHub used AI coding agents to make a previously expensive category of engineering project economically feasible while migrating a live production system incrementally.
That changes how engineering organizations should think about technical debt.
Some migrations that previously could not justify:
the people
the time
or
the opportunity cost
may now become reasonable.
But AI does not repeal the fundamental laws of software engineering.
Generated code still needs:
- architecture
- tests
- review
- observability
- rollout strategy
- debugging
- operational ownership
GitHub’s own regression experience makes that clear.
The future of AI coding may therefore be less about:
“How much code can the agent write?”
and much more about:
“How much verified change can the engineering organization safely ship?”
That is the metric that matters.
And if coding agents continue reducing the implementation cost of large migrations, software modernization may become one of the biggest enterprise use cases for AI-assisted engineering.