
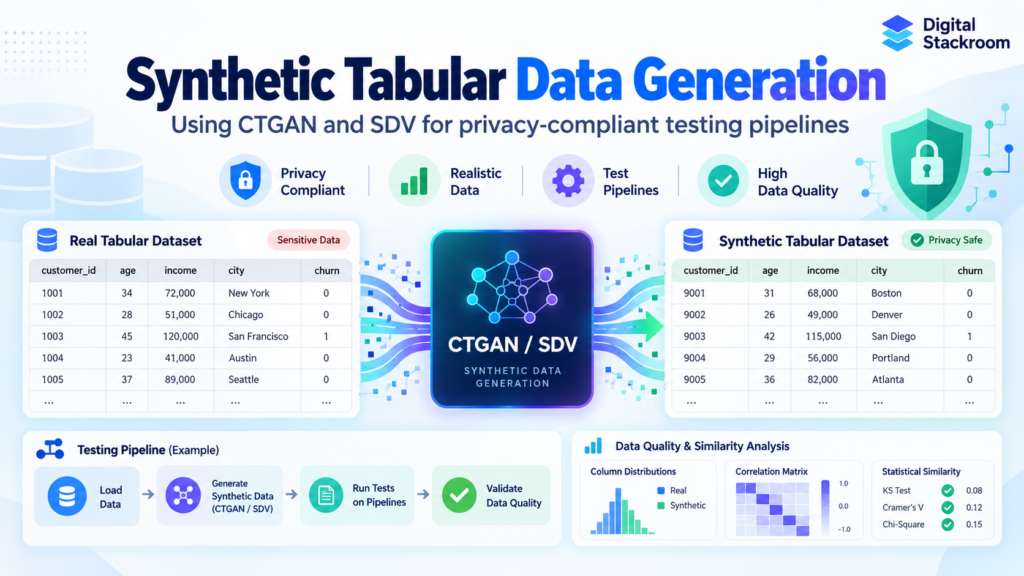
Modern engineering teams face a persistent dilemma when testing production data pipelines: staging environments require realistic, rich data distributions, but strict compliance frameworks like GDPR, HIPAA, and CCPA forbid moving raw customer data out of production networks.
Traditional obfuscation techniques—such as static regex masking, random fuzzing, or hashing—consistently fall short. Simple tokenization breaks multi-column correlations, destroys conditional distributions, and strips out edge cases necessary for validating analytics dashboards and machine learning models.
Synthetic data generation resolves this trade-off. By leveraging generative deep learning models tailored for structured records—specifically Conditional WGANs (CTGAN) implemented via the Synthetic Data Vault (SDV) ecosystem—teams can train models to learn the statistical profile, foreign key constraints, and mathematical correlations of real tables while outputting completely fabricated, privacy-safe records.
Table of Contents
1. Problem Statement: Why Data Masking Breaks Analytics Pipelines
When building analytics pipelines, feature stores, or data marts, staging workflows require test datasets that mirror real-world dynamics:
[Production Data] ──► Traditional Static Masking ──► [Broken Staging Data]
                      • Strips complex correlation
                      • Destroys continuous multi-modal spreads
                      • Skews business metrics & regression models
The Three Structural Failure Modes of Rule-Based Masking
- Broken Multi-Column Dependencies: In a banking schema, a customer’s
annual_incomeis strongly correlated with theircredit_card_limitandloan_status. Fuzzing fields independently produces impossible combinations, such as a customer earning $12,000 annually with an approved $80,000 credit line. - Loss of Non-Gaussian Distributions: Tabular attributes rarely follow clean bell curves. Financial transactions typically show extreme multi-modal clusters (e.g., micro-charges vs. large subscription bills). Static synthetic scripts often smooth out these critical operational modes.
- Category Imbalance Erasure: Fraudulent transactions or production system failures often account for less than 0.1% of historical logs. Basic random generation either ignores this tiny minority or over-indexes it, ruining pipeline testing.
2. Architecture: How CTGAN Models Tabular Data
Generating images or prose relies on continuous vectors or token sequences. Structured relational data presents unique obstacles: mixed continuous and discrete columns, severe class imbalance, and complex conditional requirements.
CTGAN (Conditional Table GAN) solves these challenges through three architectural mechanisms:
┌────────────────────────────────────────────────────────┐
│                   CTGAN ARCHITECTURE                   │
│                                                        │
│  1. Mode-Specific Normalization                        │
│     • Deconstructs multi-modal continuous columns      │
│       using a Variational Gaussian Mixture Model (VGM) │
│                                                        │
│  2. Conditional Generator                              │
│     • Conditions output vectors on specific discrete   │
│       column categories to overcome imbalanced classes │
│                                                        │
│  3. Training-by-Sampling                               │
│     • Samples representations evenly across discrete   │
│       states to prevent generator mode collapse        │
└────────────────────────────────────────────────────────┘
Mode-Specific Normalization
Continuous variables are split into a discrete representation indicating which Gaussian cluster a point belongs to, plus a scalar representing where the value falls within that specific cluster. This preserves complex spikes and long-tail distributions.
Conditional Vectors and Generator Sampling
CTGAN conditions generation on exact discrete categories. During training, minority classes are over-sampled so the generator receives equal gradient updates across both common and rare events, successfully preserving real-world edge cases.
3. Comparison: Rule-Based Mocking vs. CTGAN vs. Copulas
| Feature | Static Mocking (Faker / Random) | Gaussian Copulas | CTGAN (SDV) |
| Setup Speed | Instantaneous | Seconds | Minutes (Requires GPU/CPU training) |
| Statistical Fidelity | Zero (Static ranges only) | Moderate (Linear correlations) | High (Captures non-linear dependencies) |
| Multi-Modal Support | None | Poor | Exceptional (Mode-specific normalization) |
| Imbalanced Classes | Uniform or manually hardcoded | Skews toward majority class | Preserved via conditional vector sampling |
| Privacy Compliance | High (Pure synthetic strings) | High | High (Differential privacy options available) |
4. Hands-On Implementation: Generating Synthetic Datasets in Python
Let’s build a synthetic generation pipeline using SDV 1.x and CTGAN in Python. We will model a sensitive financial dataset featuring correlated columns, train a synthesizer, and evaluate quality scores.
Step 1: Install Required Libraries
Bash
pip install sdv pandas numpy
Step 2: Prepare the Baseline Sample Data
Python
import numpy as np
import pandas as pd

# Set deterministic random seed
np.random.seed(42)
n_records = 5000

# Synthesize a realistic sample ground truth dataframe
ages = np.random.randint(21, 65, size=n_records)
incomes = ages * 1500 + np.random.normal(5000, 8000, size=n_records)
incomes = np.clip(incomes, 20000, 250000)

tiers = []
credit_limits = []

for inc in incomes:
    if inc > 120000:
        tiers.append("PLATINUM")
        credit_limits.append(inc * 0.45 + np.random.normal(0, 3000))
    elif inc > 60000:
        tiers.append("GOLD")
        credit_limits.append(inc * 0.25 + np.random.normal(0, 1500))
    else:
        tiers.append("STANDARD")
        credit_limits.append(inc * 0.10 + np.random.normal(0, 500))

real_data = pd.DataFrame({
    "customer_id": [f"CUST-{i:05d}" for i in range(n_records)],
    "age": ages,
    "annual_income": np.round(incomes, 2),
    "account_tier": tiers,
    "credit_limit": np.round(np.clip(credit_limits, 1000, 100000), 2)
})

print(real_data.head())
Step 3: Define Metadata and Synthesizer Constraints
SDV uses explicit metadata definitions to differentiate between identifiers, numerical measurements, and categorical flags.
Python
from sdv.metadata import SingleTableMetadata

# 1. Initialize and auto-detect base schema
metadata = SingleTableMetadata()
metadata.detect_from_dataframe(data=real_data)

# 2. Mark primary identifier to avoid training noise
metadata.update_column(
    column_name="customer_id",
    sdtype="id",
    regex_format="CUST-[0-9]{5}"
)

# 3. Verify detected schema types
print(metadata.to_dict())
Step 4: Train the CTGANSynthesizer
Initialize the synthesizer and execute model training:
Python
from sdv.single_table import CTGANSynthesizer

# Configure the synthesizer
synthesizer = CTGANSynthesizer(
    metadata,
    epochs=300,
    batch_size=500,
    verbose=True
)

# Fit the generative model to the historical dataset
print("Training CTGAN synthesizer...")
synthesizer.fit(real_data)
print("Training complete.")
Step 5: Sample Synthetic Records
Once fitted, generate any desired volume of synthetic records on demand:
Python
# Generate 10,000 synthetic rows matching the production profile
synthetic_data = synthesizer.sample(num_rows=10000)

print(synthetic_data.head())
5. Evaluating Synthetic Data Quality & Fidelity
Generating data is only half the battle. You must verify that the synthetic output mirrors production distributions without memorizing or leaking real patient or customer values.
SDV provides built-in statistical validation across column shapes and bivariate trends:
Python
from sdv.evaluation.single_table import evaluate_quality

# Run formal quality audit
quality_report = evaluate_quality(
    real_data=real_data,
    synthetic_data=synthetic_data,
    metadata=metadata
)

# Inspect high-level diagnostic score
print(f"Overall Quality Score: {quality_report.get_score() * 100:.2f}%")
Understanding Diagnostic Metrics
Python
# View granular breakdown across properties
properties = quality_report.get_properties()
print(properties)
Plaintext
               Property  Score
0          Column Shapes  0.942
1  Column Pair Trends     0.918
- Column Shapes (Marginal Distribution): Measures whether individual columns in the synthetic dataset have the same mean, median, variance, and quantile distributions as real data using Kolmogorov-Smirnov (KS) and Total Variation Distance (TVD) tests.
- Column Pair Trends (Correlation Fidelity): Verifies that correlation coefficients between pairs of columns (such as
annual_incomevs.credit_limit) are preserved accurately in the generated output.
6. Exporting to Production Staging & CI/CD Pipelines
Save the trained synthesizer model as a serialized artifact to incorporate it directly into CI/CD integration pipelines:
Python
# Save trained artifact
synthesizer.save("models/financial_data_synthesizer.pkl")

# Load artifact inside CI/CD test runner
from sdv.single_table import CTGANSynthesizer

loaded_synthesizer = CTGANSynthesizer.load("models/financial_data_synthesizer.pkl")
test_batch = loaded_synthesizer.sample(num_rows=2500)

# Write directly to PostgreSQL or BigQuery staging table
# test_batch.to_sql("staging_customers", engine, if_exists="replace")
7. Production Best Practices & Privacy Safeguards
- Strip High-Cardinality Text Before Training: Do not pass raw free-text fields (such as notes or comment logs) directly into CTGAN. Strip or tokenize them first, as unstructured text can bloat model parameters and increase memorization risk.
- Implement Membership Inference Defense: Check for overfitting by calculating nearest-neighbor distances between synthetic rows and real training records. If synthetic records match real rows identically across multiple continuous dimensions, reduce training epochs or add differential privacy noise.
- Persist Pre-Flight Assertion Gates: Run automated data checks on synthetic output—using our framework for automating data validation pipelines with SQL assertion checks—before promoting test tables.
- Leverage GPU Acceleration: While CTGAN trains on standard CPU instances, leveraging an NVIDIA GPU via CUDA shortens training times on datasets over 100,000 records from hours to minutes.
By combining Conditional GANs with systematic quality reporting, data teams can deploy realistic, privacy-compliant test environments that reflect true production dynamics without compliance exposure.